Last Update: 11/04/2026
I am joining Télécom Paris as an Assistant Professor with the Audio Data Analysis and Signal Processing (ADASP) group at Laboratoire LTCI, starting in November 2026! Before that, I was a Senior Researcher on Spatial Audio and Multimodal AI at Dolby Laboratories. I obtained my PhD from the Audio Information Research Lab, University of Rochester, NY, USA. I was fortunate to work with Prof. Zhiyao Duan during my PhD. Take a look at my CV.
My research focuses on applied machine learning, particularly in speech and audio processing. My long-term vision is to build human-centric multimodal AI systems for audio, systems that understand, generate, and adapt speech and audio in ways that are both immersive and trustworthy. This spans spatial audio, audio-visual learning, and audio deepfake detection, sitting at the intersection of machine listening, multimodal learning, and generative modeling for audio. My research contributions have been showcased at prestigious venues such as ICASSP, WASPAA, Interspeech, SPL, TMM. I received recognition through the Rising Star Program in Signal Processing at IEEE ICASSP 2023, the Graduate Research Fellowship Program from National Institute of Justice, IEEE Signal Processing Society Scholarship, and IEEE WASPAA Best Student Paper Award.
I am open to collaborations. I will be recruiting PhD students starting Fall 2027. Feel free to reach out at you.zhang@ieee.org if you’re interested!
Research Areas
Spatial Audio
Personalized HRTF modeling with neural fields and perception-informed learning.
Key paper: WASPAA 2025 →
Audio Deepfake Detection
Generalizing detection of synthetic speech and singing voices to unseen attacks.
Key paper: SPL 2021 →
Audio-Visual Learning
Multimodal models linking sound and vision, such as speech-driven talking faces.
Key paper: TMM 2022 →
News
- 2026/10 My PhD thesis is available online! UR Library ProQuest.
- 2026/10 I attended DCASE 2026 at Tufts and SANE 2026 at MIT.
- 2026/09 I attended DAFx 2026 at MIT and presented a tutorial with Yoshiki Masuyama, titled “From Neural Fields to Personalized Spatial Audio: A Hands-on Tutorial on HRTF Modeling”. Code Slides
- 2026/07 I gave a talk on audio deepfake detection at Duke Kunshan University (DKU). Thank Prof. Xiaoxiao Miao for the invitation!
- 2026/06 I gave a guest lecture on audio deepfake detection at National Taiwan Univeristy. Thank Prof. Shao-Yuan Lo for the invitation!
- 2026/04 I gave a job talk at Télécom Paris, titled “Towards Human-Centric Multimodal Generative Audio AI”. Slides
- 2026/04 I successfully defended my PhD! Presentation title: Toward Trustworthy and Immersive Audio Experiences.
- 2026/02 I gave a talk at Centre for Digital Music at QMUL on “From Neural Fields to Perception-Informed Learning: Scalable and Perceptually Grounded HRTF Personalization”. YouTube Slides Info on C4DM web
- 2026/01 Two papers accepted by IEEE ICASSP 2026. Congrats, Kun and Xuanjun!
- 2025/12 I attended ASA/ASJ and IEEE ASRU at Honolulu, HI.
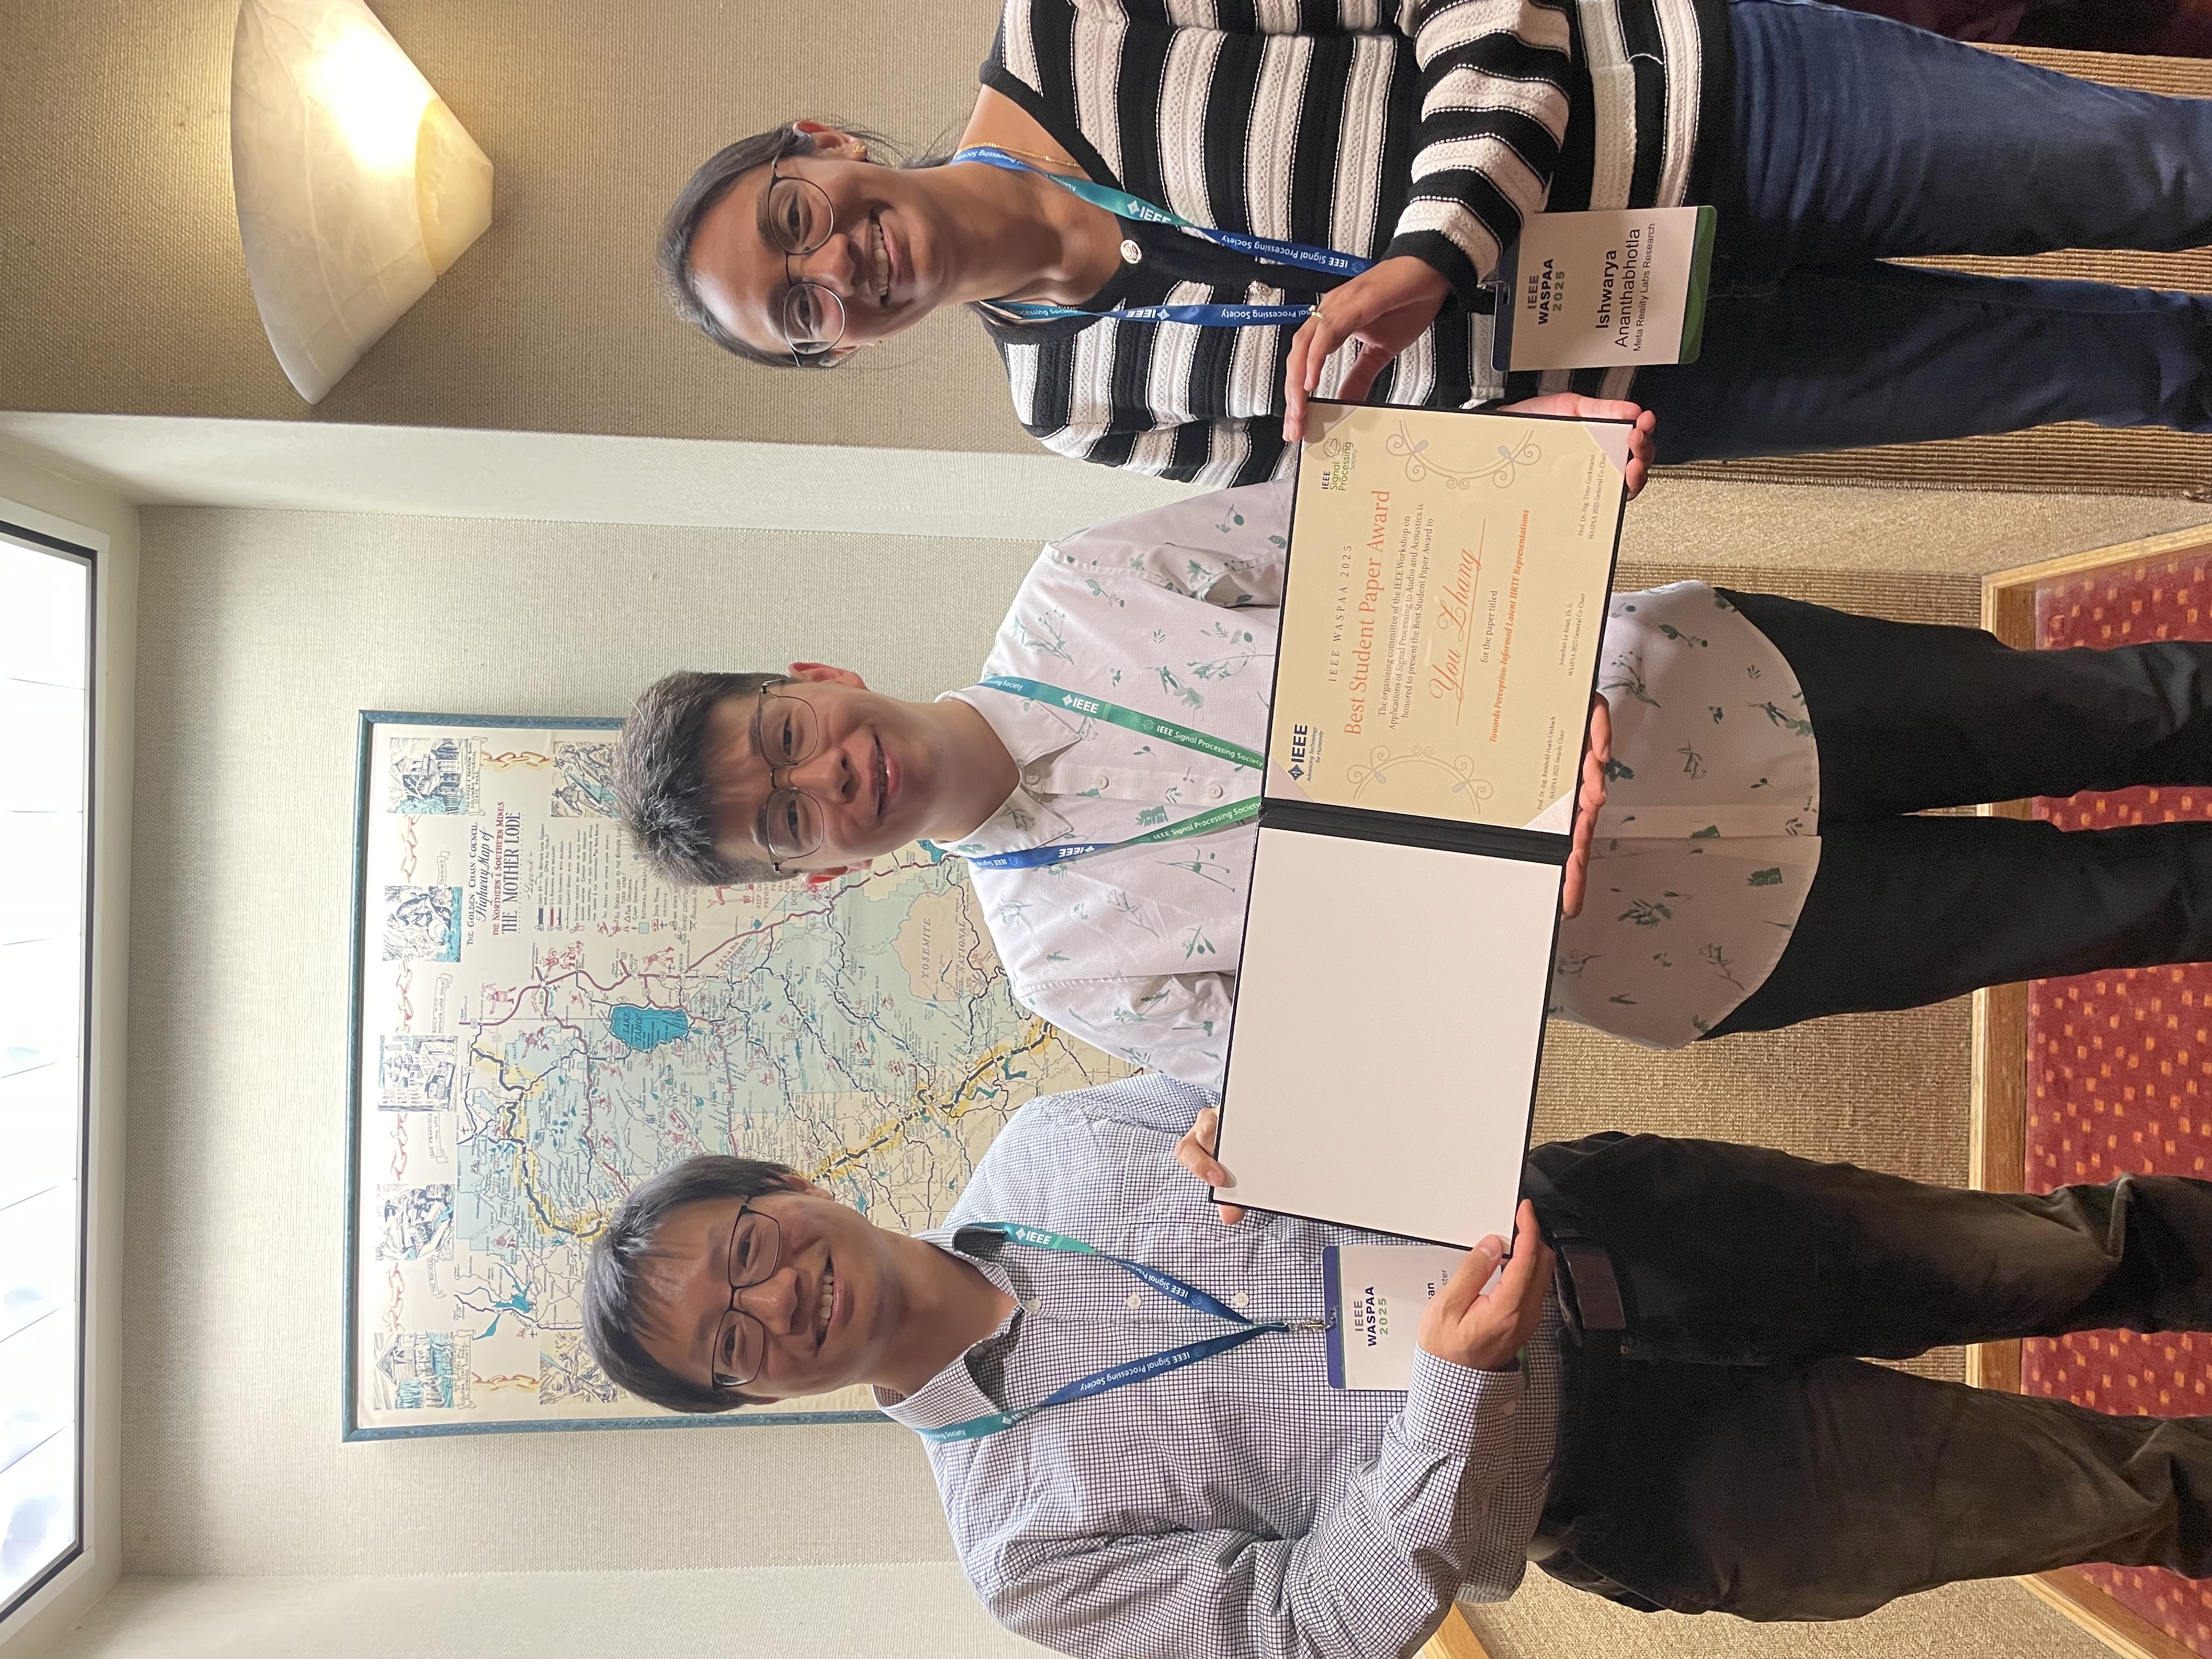
- 2025/10 I attended IEEE WASPAA 2025 at Lake Tahoe and won the Best Student Paper Award, then presented the work also at SANE!
- 2025/09 A review paper on ML for acoustics is open access online, published on npj Acoustics!
More archived news.
- 2025/07 One paper accepted by IEEE WASPAA 2025!
- 2025/06 I joined Dolby Lab at Atlanta as a Senior Researcher!
- 2025/06 One paper accepted by Interpseech 2025 and one paper accepted by IEEE ICIP 2025!
- 2025/04 I received Open Scholarship Awards from OSC Rochester for commitment to openness in academic research!
- 2024/12 We are organizing the SVDD special session @ IEEE SLT 2024!
- 2024/11 I was awarded the IEEE SPS Scholarship! Thank you, IEEE Signal Processing Society!
- 2024/10 I attended Boston AI Music Meetup and SANE 2024.
- 2024/09 Our new WildSVDD challenge is held successfully at MIREX @ ISMIR 2024!
- 2024/08 Our SVDD challenge overview paper is accepted by IEEE SLT 2024!
- 2024/08 One paper accepted by MMSP 2024. Congrats, Kyungbok!
- 2024/07 We presented our tutorial on “Multimedia Deepfake Detection” at ICME 2024.
- 2024/05 I joined Meta Reality Labs Research Audio as a Research Scientist Intern, working with Dr. Ishwarya Ananthabhotla.
- 2024/04 I gave a 1-hour tutorial on “Personalizing Spatial Audio: Machine Learning for Personalized Head-Related Transfer Functions (HRTFs) Modeling in Gaming” at 2024 AES International Conference on Audio for Games. Slides
- 2024/04 I attended NEMISIG 2024, NYC Computer Vision Day 2024 and ICASSP 2024.
- 2024/04 Exciting milestone achieved! I have successfully passed my PhD proposal/qualifying exam on “Generalizing Audio Deepfake Detection”. Looking forward to embarking on this fruitful road!
- 2024/04 Our inaugural Singing Voice Deepfake Detection (SVDD) 2024 Challenge proposal has been accepted by IEEE Spoken Language Technology Workshop (SLT) 2024! Check out the challenge website here! Registration deadline: June 8th.
- 2024/03 I gave a talk at GenAI Spring School and AI Bootcamp on “Audio Deepfake Detection”.
- 2024/02 I was delighted to share insights on detecting audio deepfakes in a recent piece by NBC News.
- 2023/12 I gave a talk at Nanjing University on “Improving Generalization Ability for Audio Deepfake Detection”. Slides
- 2023/12 Two papers accepted by ICASSP 2024. (SingFake and Speech Emotion AV Learning) Congrats, Yongyi and Enting!
- 2023/11 I sat down with Berkeley Brean at News10NBC to talk about audio deepfake detection. WHEC-TV Link Tweet1 Tweet2 Hajim Highlights
- 2023/11 I attended WASPAA, SANE, NRT Annual Meeting, and BASH to present our work on personalized spatial audio. Busy but exciting two weeks!
- 2023/10 Received National Institute of Justice’s (NIJ) Graduate Research Fellowship Award. NIJ Description UR News Center Hajim Highlights
- 2023/07 One paper accepted by WASPAA 2023. Congrats, Yutong!
- 2023/06 Our paper “HRTF Field” was recognized as one of the top 3% of all papers accepted at ICASSP 2023. Hajim Highlights
- 2023/05 Recognized as one of the ICASSP Rising Stars in Signal Processing. poster
- 2023/05 One paper accepted by Interspeech 2023. Congrats, Yongyi!
- 2023/02 Two papers accepted by ICASSP 2023. (HRTF Field and SAMO) Congrats, Siwen!
- 2023/02 Delivered a talk at ISCA SIG-SPSC webinar, titled “Generalizing Voice Presentation Attack Detection to Unseen Synthetic Attacks”. slides
Selected Publications
(For full list, see my Google Scholar profile or my Publications page.)
[4] You Zhang, Andrew Francl, Ruohan Gao, Paul Calamia, Zhiyao Duan, and Ishwarya Ananthabhotla, Towards Perception-Informed Latent HRTF Representations, in Proc. IEEE Workshop on Applications of Signal Processing to Audio and Acoustics (WASPAA), 2025. DOI arXiv video slides poster notebookLM Best Student Paper Award, IEEE WASPAA 2025
[3] You Zhang, Yongyi Zang, Jiatong Shi, Ryuichi Yamamoto, Tomoki Toda, and Zhiyao Duan, SVDD 2024: The Inaugural Singing Voice Deepfake Detection Challenge, in Proc. IEEE Spoken Language Technology Workshop (SLT), 2024. DOI arXiv code illuminate webpage
[2] You Zhang, Yuxiang Wang, and Zhiyao Duan, HRTF Field: Unifying Measured HRTF Magnitude Representation with Neural Fields, in Proc. IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), 2023. DOI arXiv code video illuminate Recognized as one of the top 3% of all papers accepted at IEEE ICASSP 2023
[1] You Zhang, Fei Jiang, and Zhiyao Duan, One-Class Learning Towards Synthetic Voice Spoofing Detection, IEEE Signal Processing Letters, vol. 28, pp. 937-941, 2021. DOI arXiv code video poster slides project illuminate